About the standard .csv export format

I want to export to .csv, and as a beginner, I was happy to accept the built-in default conversion. Until I tried it.

If there are multiple artists in the Artist tag, separated by linebreaks, the standard export simply exports the tag, linebreaks and all. That results in an invalid .csv file, because the consuming program interprets those linebreaks as structural record breaks, not data. I consider that behaviour as downright wrong. One solution is to escape or disguise linebreaks in the data of a single cell. I understand that not everybody might want that, but it is reasonable to expect that as the default behaviour of the built-in conversion.

I am well aware that there is no such thing as a standard .csv file, but as a general practical standard, producing a file that Excel will not mangle is a good approach. As it is, there is no simple way to detect and repair the structural errors that the built-in .csv export introduces.

I realize also that there are probably ways to achieve this myself. But my point is, for something as basic as this, I should not have to do that.
I think that your expectation is not quite right.
The also shipped export scripts are examples which you can take as a template and adapt them according to your requirements. The templates illustrate the structure and the basic application of the syntax.

Esp. the example that you used as proof that the sample script is not up to the mark is by far no ordinary one:

is not beyond the standard but I wonder how your target player copes with such data. So far most players accept either real multi-value fields or like separators like commas, semicolon or slash.

If you need assistance to adapt the csv template for your use case, then please say so.

One thing that I have asked several times but have never gotten an answer to: which function do you find in Excel but not in MP3tag so that it is worth the effort to use an export script, possibly adapt it, read in the data in Excel, export it from Excel and import it again in MP3tag so that the modification gets written to the files.

My expectation is that a built-in function to produce a .csv file should produce, in fact, a .csv file. You think that is not quite right. I think it is eminently reasonable.

I don't want it in Excel. The only reason for bringing Excel into the picture is to demonstrate the built-in export produces a broken file. In the absence of a standard, "Excel can't handle it" is a reasonable way to determine broken.

Never mind why I want the file. It is not for a player, nor for Excel.

As for saying it is worth the effort to use the existing script and adapt it: Give me a program in a templating language I don't know, and which is sketchily documented, I can probably figure out a way to fix it. But all I have is a broken program in a language I don't know.

unfortunately you jumped over a small but important detail:

The built-in function is the export function which produces a text file as output and interprets scripting functions.
This feature can also be used to produce files that can be imported by programs that use CSV as format.
Other formats are HTML, RTF and even laTex. Some have tried xml. Plain text is also possible, of course.

If you are looking for something

see here

here:

and here:

and in general

I accept that the code is an example. I just think it should be a working example. Embedded carriage returns in a tag are not exactly rare. Anyone who is producing a .csv file will run into this problem. I think it is fair to expect example code to anticipate this problem and provide a solution.
Anyhow, this exchange has convinced me that I have spent enough time trying to get mp3tag to do this for me. I will just go and write a program to extract the tags myself. If I had done that at the start, by this stage it would be almost ready for testing.

While you are writing your program, also take care to mask all the commas and semicolons that may pop up in your data - they are also a problem in CSV files.

For the linebreaks and a quick text export that would work in Excel i suggest the function
Edit>Copy as text
Format string: $replace($columnValues(,$char(9)),$char(13)$char(10),#)

Like I said, Excel was only a way for me to make my point. It is not the target. Thanks for your advice, but I need no help writing a Python program to do this.

It does work, provided you don't have pathological data. The purpose of an example is to be easily understandable, so that beginners can see how things work and adapt the code to their own needs, not to cover every conceivable edge case out of the box.

Newlines in a CSV data field are perfectly fine btw., as long as the field is quoted. So %artist% becomes "%artist%". But now you have to escape quotes that might be part of the data. That makes it "$replace(%artist%,","")". But %artist% can also be a multi-value field, and if you don't want to lose all entries but the first, that becomes "$replace($meta_sep(artist,\\),","")". Note that %artist% becomes just artist within the meta functions. Now do the same for %title% and %album%.

%_folderpath% and %_filename_ext% are a bit easier, at least on Windows. While filenames may contain commas or semicolons and therefore should be quoted, they can't have newlines, quotation marks, or multi-values.

But you also want to make sure that numerical columns contain only digits if the importing program auto-detects data types, so %track% becomes $num(%track%,1) and %year% becomes $num(%year%,1). And we're even ignoring badly formatted data here with values outside a sensible range, like track number 0 or year 999999.

Implement all of this, and line 2 of the example file

$loop(%_filename_ext%)%title%;%artist%;%album%;%track%;%year%;%_length_seconds%;%_file_size%;%_file_mod_date%;%_folderpath%;%_filename_ext%;

becomes

$loop(%_filename_ext%)"$replace($meta_sep(title,\\),","")";"$replace($meta_sep(artist,\\),","")";"$replace($meta_sep(album,\\),","")";$num(%track%,1);$num(%year%,1);%_length_seconds%;%_file_size%;%_file_mod_date%;"%_folderpath%";"%_filename_ext%";

How would that be a simple example to explain the basics of an export script?

The data is not pathological. This is a .flac file with multiple values for the Artist field, and download platforms like Qobuz (which is where I got the file) separate multi-valued tags in the physical file container using linefeeds. Picard knows this, and displays the four values on separate lines as expected. That happens with 1% of my collection, 179 files out of 17,876.

If the purpose of the example is to demonstrate how to loop through the data, then producing a text file would be just as informative. If the purpose of the example is to demonstrate how to loop through the data to produce a .csv file, then it is not fit for purpose, because linefeeds in the data are normal, so the resulting file may be broken. A .csv that is only 99% formally valid is 100% useless.

Your ingenious fix to the code may not be simple, but it does show it is nontrivial to get a working .csv file. If that were the example, then a beginner could simply use it as is, and have something useful. And perhaps, with more familiarity with the templating language, could acquire sufficient skill to do something similar themselves. Writing a correct .csv file is very far from the simple task novices usually think it is. The burden of your argument is, "Yes, it is a naive little program, that is simple to understand. It won't work, of course, but the idea is the important thing. If you want valid output, well, then you are on your own." By sweeping real difficulties under the carpet, you are not making things easier for the beginner. It is better for them to understand up front that a .csv is not just a textfile with a couple of extra commas.

If it is reasonable for the sample HTML exports to take care of translating & to & to avoid producing broken HTML (in my case, 2% of files), why is it unreasonable to expect that a .csv export will likewise not embed unescaped linefeeds in column data?

I saw that mp3tag had an export facility that claimed to support .csv files. How nice!, I thought. Had I known that I would be expected to negotiate the subtleties of the .csv format myself, in a language I don't know, I could have saved myself time and aggravation, by going straight to a Python solution.

The supplied export configurations are intended as starting points for learning and customization, not as full-fledged exporters for every use case. I should have made that distinction clearer. I understand that you wanted a usable CSV export, not to spend time learning Mp3tag's scripting language to make one.

That said, your criticism of the CSV example is valid. Multiple artist values and line breaks are normal metadata, and the current template doesn't quote fields correctly when they occur.

I've added this to my internal wish list and will review how the example is presented and whether it can handle these common cases without losing its value as a simple starting point. Suggestions for keeping it approachable while producing usable CSV are welcome.

I don't know much about flac tags. Is there an official standard that defines linefeeds as field separator? If so, Mp3tag should probably handle that on import and create a multi-value field, rather than a single multi-line field. That would be a separate bug report. If it is not an official standard, however, but just a Qobuz quirk, then it is pathological data.

Can you provide a screenshot? If it displays four lines of text in the metadata panel, then it does not treat it as a multivalue field, but reads the linefeeds literally, just as Mp3tag apparently does. A multivalue field would be shown on a single line, with "; " (semicolon, space) as a separator. You would have to open the "Edit Tag" dialog to see the four separate values.

Except it doesn't. How did you get that notion?

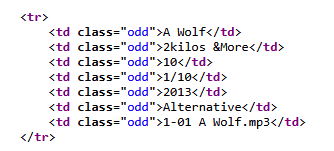
The name of the band "2kilos &More" (sic) is written to the HTML file literally, without escaping the &. I also have tracks from a band whose name is "<1979>", where the <> is not escaped either.

Maybe include two versions - a bare bones script clearly marked as example, and a fully functional one that handles all the special cases, too?

There is probably one ARTIST field that contains the different artists, e.g.,

Artist1
Artist2
Artist3

Parsing that as separate artists automatically is not something I would add.

It would be \\ in Mp3tag, which is the separator that denotes multiple fields in the Tag Panel and the File List.

This might be a version that conforms to CSV, preserves linebreaks, and is still simple enough to be understood with a little effort.

$filename(csv,utf-8)Title;Artist;Album;Track;Year;Length;Size;Last Modified;Path;Filename
$loop(%_filename_ext%)"$replace($meta_sep(title,$char(10)),","")";"$replace($meta_sep(artist,$char(10)),","")";"$replace($meta_sep(album,$char(10)),","")";"$replace($meta_sep(track,$char(10)),","")";"$replace($meta_sep(year,$char(10)),","")";"$replace(%_length_seconds%,","")";"$replace(%_file_size%,","")";"$replace(%_file_mod_date%,","")";"$replace(%_folderpath%,","")";"$replace(%_filename_ext%,","")"
$loopend()

I decided to include a slightly modified version with Mp3tag v3.37-beta.5

$filename(csv,utf-8)Title;Artist;Album;Track;Year;Length;Size;Last Modified;Path;Filename
$loop(%_filename_ext%)"$replace($meta_sep(title,; ),","")";"$replace($meta_sep(artist,; ),","")";"$replace($meta_sep(album,; ),","")";"$replace($meta_sep(track,; ),","")";"$replace($meta_sep(year,; ),","")";"$replace(%_length_seconds%,","")";"$replace(%_file_size%,","")";"$replace(%_file_mod_date%,","")";"$replace(%_folderpath%,","")";"$replace(%_filename_ext%,","")"
$loopend()